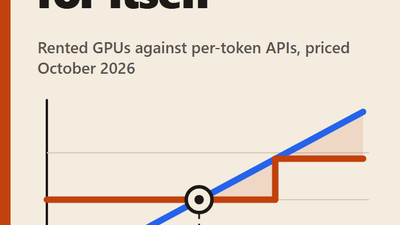
AI LLM APIs & SDKs Self-Hosting an LLM: The Break-Even Point in Numbers Self-hosting an LLM looks cheap on a whiteboard. An H100 rents for a few dollars an hour, an 8B model...
AI Claude Opus 5.5: Breaking Changes and What It Really Costs Anthropic released Claude Opus 5.5 on 22 September 2026 at $4 per million input tokens and $20 per million output,...
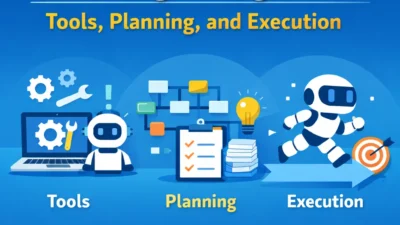
AI Building AI Agents: Tools, Planning, and Execution AI agents represent a shift from single-response language models to goal-driven systems. Instead of answering one prompt, an agent can...
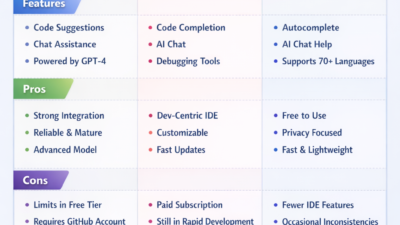
AI AI Code Assistants Compared: Copilot vs Cursor vs Codeium AI code assistants have moved from novelty to daily tooling for many developers. However, not all assistants solve the same...
AI Fine-Tuning vs RAG: When to Use Each Approach As large language models mature, developers face a recurring question: should you fine-tune a model, or should you use retrieval-augmented...
AI Building an AI Chatbot with Streaming Responses A chatbot that waits several seconds before responding feels slow, even if the answer is correct. Streaming responses solve this...
AI Prompt Engineering Best Practices for Developers Prompt engineering is not about clever wording. In production systems, it is about reliability, control, and predictability. A prompt that...
AI Vector Databases Compared: Pinecone vs Weaviate vs Chroma Vector databases play a central role in modern AI systems. However, choosing the right one often causes confusion. This vector...
AI RAG (Retrieval-Augmented Generation) from Scratch Large language models are powerful, but they do not know your data. Retrieval-augmented generation (RAG) solves that gap by combining...