RAG & Vector Search Qdrant Setup and Python Integration: Hands-On Guide If you are building a RAG pipeline or a semantic search feature and want a Rust-based vector store that runs...
RAG & Vector Search pgvector in Postgres: RAG Without a Separate Vector DB If you are building a RAG application and already run Postgres, adding a second database just for embeddings often creates...
RAG & Vector Search Reranking in RAG: Cohere Rerank and Cross-Encoders Guide If your RAG pipeline retrieves chunks that look relevant but produce vague answers, the problem is rarely the embedding model....
RAG & Vector Search Hybrid Search in RAG: Combining Keyword and Vector Retrieval If your RAG pipeline misses obvious matches — a user types an exact error code, a SKU, or a function...
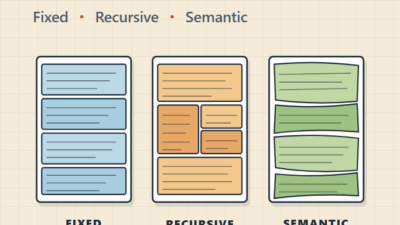
RAG & Vector Search RAG Chunking Strategies: Fixed, Recursive, and Semantic If your retrieval-augmented generation system surfaces documents that contain the right keywords but miss the actual answer, your chunking step...
LLM Gateways & Routing Portkey AI Gateway: Caching, Fallbacks, and Observability If you ship LLM features to real users, three problems show up fast: OpenAI returns a 500, your bill doubles...
LLM Gateways & Routing Bifrost vs LiteLLM: When 50x Faster Actually Matters If you are building an LLM app that talks to OpenAI, Anthropic, and a few open-source models, you have probably...
LLM Gateways & Routing LiteLLM Setup: Unified Proxy for Multi-Provider LLMs If your application talks to OpenAI today and you suddenly need Claude for long-context tasks, Gemini for vision, and a...
LLM APIs & SDKs Groq API: Fastest LLM Inference for Real-Time Apps If you have ever built a voice assistant, a live coding helper, or a chat product that streams tokens, you...